


TDM — Table Implementation
TDM enables users to provision tables in a TDM task. To do this, users can select one of the following two options:
- Business Entities and referential data. The included tables are related to the task's Business Entities (BEs) and are required in the testing environment.
- Tables — starting with TDM V9.X, the TDM provides the option to select a list of independent tables from multiple DBs that relate to the source environment, without any relation to a Business Entity. This option is useful when processing standalone tables rather than business-driven entities.
Users can either store the extracted tables in Fabric for later use, or set the task retention period to Do not retain to load the tables directly into the target environment without persisting them in Fabric. If the processed tables contain complex fields (for example, JSON), the task retention period must be set to Do not retain.
Each table is stored in Fabric within the TDM_TableLevel LU. Each task execution stores every table as a separate LU Instance (LUI), representing an independent data snapshot.
For example, running two executions of a task that extracts the Product_Mapping table results in two separate LUIs in the TDM_TableLevel LU.
Click here for more information about table processing during task execution
Tables - LUI Format
Tables without partitions
[source environment name]|[DB interface name]|[DB schema name]|[table name]|[task execution id]
Examples:
SRC|CRM_DB|public|case_note|102822
SRC|CRM_DB|public|case_note|102826
SRC|BILLING_DB|public|contract_offer_mapping|102826
Partitioned Tables
Starting with TDM 9.5 onwards, the performance of table-level tasks has been improved by processing table partitions in parallel, significantly reducing execution time for large tables.
Each table partition is handled as a separate LUI by the task execution batch process for extract or extract & load processes.
LUI format:
[source environment name]|[DB interface name]|[DB schema name]|[table name]|[task execution id]|[partition number]
Example:
- Production|CRM_DB|public|customer|45|2
TDM_TableLevel LU Tables
Each LUI contains the following tables:
TDM_REF_ROOT
A dynamic SQLite table, which has the same structure as the source table and contains the extracted table records. The naming convention for this table is:
__t_<source table name>
- The following is an example of how a case_note table record is inserted into the SQLite dynamic table:
/*sqlite*/ insert into TDM_TableLevel.__t_case_note (case_id,note_id,note_date,note_text) values(?,?,?,?);
Note:
- In previous TDM versions, tables were saved in the TDM_Reference LU. However, as this LU is no longer used (starting with TDM V9.0), the tables must be re-extracted into the new TDM_TableLevel LU.
Tables — Implementation Steps
Step 1: Deploy the TDM_TableLevel LU
Import the TDM_TableLevel LU and deploy it.
Step 2: Optional — Populate RefList MTable
This step is required for:
- Entities & referential data tasks. Populate the RefList with a list of all available related tables for each LU. The following settings should be populated for each record.
- Table-level tasks for tables whose source and target attributes are not identical.
The RefList MTable contains the following fields:
lu_name — Populated by the LU name to allow selection of the related table in a TDM task based on the task's LUs. Alternatively, if you wish to run the table in a table-level task, populate the lu_name with TDM_TableLevel.
id — An incrementing number.
reference_table_name — Populated with the table name in the source environment.
interface_name — The table's source interface.
schema_name — Populated with the name of the source DB schema that stores the table.
target_ref_table_name — An optional parameter. Populate it when the table names in the source and target differ. If not provided, the target table name is taken from the reference_table_name field.
target_interface_name — The table's target interface.
target_schema_name — Populated with the name of the target DB that stores the table.
table_pk_list — An optional setting. Populated with the list of the target table's PK fields in the RefList object. These fields can be used later for customizing the load flow to run an Upsert on the target table.
truncate_indicator — By default, TDM runs a delete on the table in the target environment before loading it. If you have permission to run a truncate on the target table and need to use the truncate instead of delete (e.g., the target DB is Cassandra), set this indicator to true.
count_indicator — This setting is set to true by default, enabling counting the number of records in the source or target, as a way to monitor task execution. Set this indicator to false, if required, to disable counting records in the target.
count_flow - Populated with the name of a customized flow that returns the table record count. The flow must expose a single external output parameter named tableCount.
Starting with TDM V9.4, the schema_name and target_schema_name fields can be populated using either of the following options:
- Schema name – Specify the schema name directly.
- Global name – Enclose the Global name with
@signs to indicate that the schema name should be retrieved from the Global's value. For example:@CUSTOMER_SCHEMA_NAME@.
Using a Global to populate the schema name is useful when different environments use different schema names.
Note: If the table is partitioned and therefore has a record in the TableLevelDefinitions MTable, populate the TableLevelDefinitions.schema_name field with the Global name as well, using the same syntax as in the RefList MTable (for example, @CUSTOMER_SCHEMA_NAME@).
Click here for more information about MTable objects.
Supporting Different Source and Target Settings
By default, you can populate the RefList MTable to support different source and target settings.
Starting with TDM 10.1, you can also implement a custom Broadway flow to map different source and target settings. The custom flow must have the same inputs and outputs as the DefaultSourceTargetMappingData flow.
To use the custom flow, specify its name in the table_info_mapping_flow field of the TableLevelDefinitions MTable.
Step 3: Catalog
Edit the PII Settings
The TDM table flow uses Fabric Catalog masking. You can edit the PII settings in the Catalog when required.
Run the Catalog to Identify Table Relations and Order
Run the Discovery job on the table's interfaces. Following the job completion, the interface metadata is retrieved from the Catalog.
Optional – Catalog Settings for Table-Level Task Improvements
Add Field Aliases to Table Fields
Starting with TDM 10.1, table-level task filters can display friendly business names for table fields. Field aliases also enable users to share a filter across multiple tables in a task when the corresponding fields have the same business name.
For example, a filter on Financial Transaction Type = 'Payment' can be shared across multiple tables that contain fields with the same business name.
To enable this functionality, tag the relevant table fields with the fieldAlias attribute in the Fabric Catalog. This displays their business names in the filter definition and enables cross-table filter sharing.
See the example below:
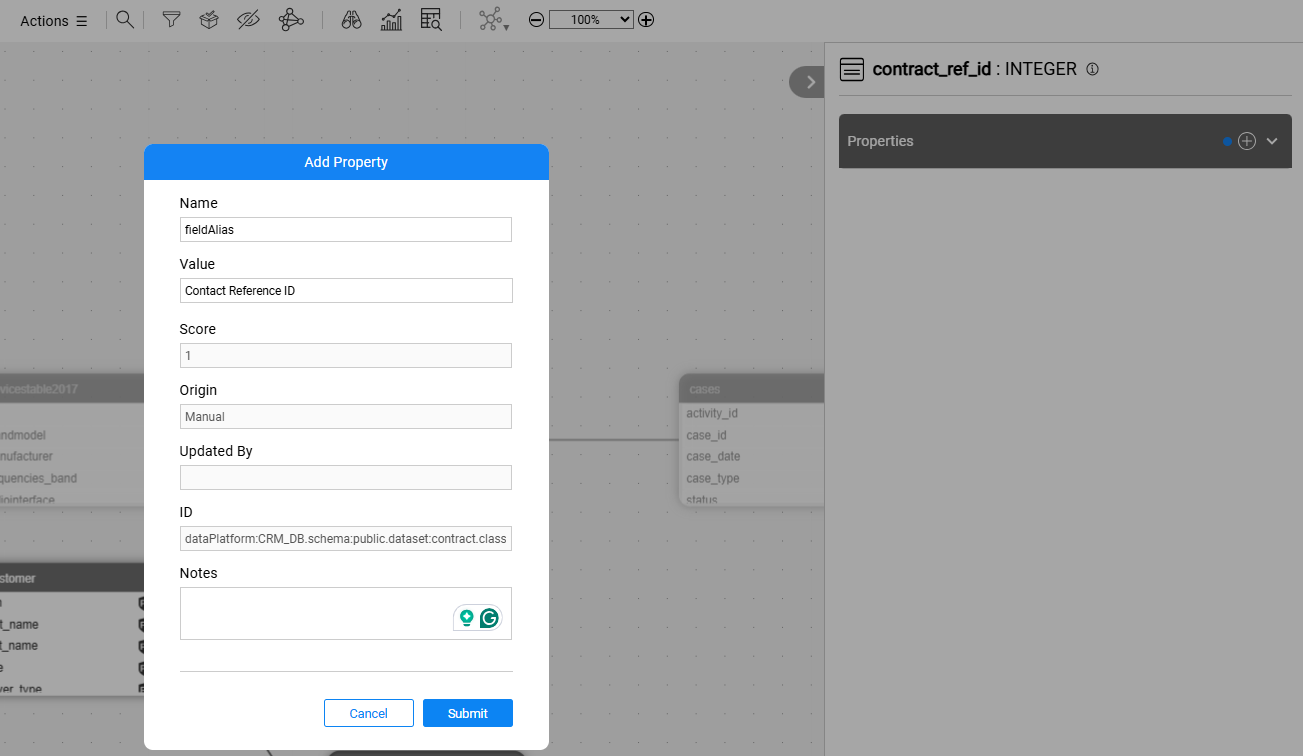
For more information, see Manual Overrides on Table Fields in the Catalog.
Add Option Set Analyzer to Discovery
Use the Option set analyzer plugin during discovery to identify non-sensitive (non-PII) fields with a limited number of distinct values in the sampled data. The plugin saves the identified values in a dedicated MTable, making them available as selectable options in table-level task filters.
For example, the vip_status field may contain the following values: Bronze, Silver, Gold, and Platinum. When defining or running a task, users can select a value from the available list or enter a custom value manually.
For more information about how to add filters to tables in a task, click here.
Step 4: Optional — Special Handling
Interface Level Special Handling
The TableLevelInterfaces MTable enables implementors to exclude interfaces from the table-level tasks or define special handling rules for a given interface.
By default, this MTable is populated with the TDM and POSTGRESQL_ADMIN interfaces in order to prevent the TDM tasks from selecting the TDM tables. It is possible to populate additional DB interfaces, either to exclude them from table selection in the TDM task or to apply special handling to their tables. Each DB interface requires its own record. The following settings should be populated for each record:
- interface_name — the interface name defined in the TDM project implementation.
- suppress_indicator — when set to true, the DB tables are excluded from the selection of tables in a TDM task; when set to false, the interface's tables can be selected in a TDM task.
- truncate_indicator — by default, TDM runs a delete on the table in the target environment before loading it. If you have permission to run a truncate on the target table and need to use the truncate instead of delete (e.g., the target DB is Cassandra), set this indicator to true.
- no_schema — this indicator is used for interfaces without a DB schema, where the JDBC connector adds a schema for them. For example: CSV files. The CSV JDBC Connector extension concatenates the 'main' schema name to the file list. Setting this field to true would ignore the concatenated schema when accessing the files.
Tables Implementation — Special Handling
TDM enables customization of the default task execution logic for a specific interface type, interface, schema, or table, including the following capabilities:
- Adding customized flows.
- Configuring commit_size in TableLevelDefinitions to control the number of records reported to the task execution monitor (report every X records).
- Disabling record counting, or adding a flow to count records, to provide the total number of records for processing to the task execution monitor Click here for more details.
- Starting with TDM 9.5, supporting concurrent processing of table partitions.
- Starting with TDM 9.5, supporting in-place masking tasks on tables.
- Supporting table-level tasks using Connectors, for example MongoDB.
Step 5: Optional — Pre and Post Execution Processes
Starting with TDM 10, table-level tasks support pre and post execution processes. To make these processes available for selection when creating a table-level task, the implementor must populate the TableLevelPostAndPreExecutionProcess MTable.
The MTable contains the following fields:
- Process_name — The name of the Fabric flow to execute as a pre or post execution process.
- Process_type — The type of process: pre (runs before the task execution) or post (runs after the task execution).
- Execution_order — The numeric order in which the process runs relative to other processes of the same type. Lower numbers run first.
Once the MTable is populated, the configured processes become available for selection in the task's pre and post execution process settings.


TDM — Table Implementation
TDM enables users to provision tables in a TDM task. To do this, users can select one of the following two options:
- Business Entities and referential data. The included tables are related to the task's Business Entities (BEs) and are required in the testing environment.
- Tables — starting with TDM V9.X, the TDM provides the option to select a list of independent tables from multiple DBs that relate to the source environment, without any relation to a Business Entity. This option is useful when processing standalone tables rather than business-driven entities.
Users can either store the extracted tables in Fabric for later use, or set the task retention period to Do not retain to load the tables directly into the target environment without persisting them in Fabric. If the processed tables contain complex fields (for example, JSON), the task retention period must be set to Do not retain.
Each table is stored in Fabric within the TDM_TableLevel LU. Each task execution stores every table as a separate LU Instance (LUI), representing an independent data snapshot.
For example, running two executions of a task that extracts the Product_Mapping table results in two separate LUIs in the TDM_TableLevel LU.
Click here for more information about table processing during task execution
Tables - LUI Format
Tables without partitions
[source environment name]|[DB interface name]|[DB schema name]|[table name]|[task execution id]
Examples:
SRC|CRM_DB|public|case_note|102822
SRC|CRM_DB|public|case_note|102826
SRC|BILLING_DB|public|contract_offer_mapping|102826
Partitioned Tables
Starting with TDM 9.5 onwards, the performance of table-level tasks has been improved by processing table partitions in parallel, significantly reducing execution time for large tables.
Each table partition is handled as a separate LUI by the task execution batch process for extract or extract & load processes.
LUI format:
[source environment name]|[DB interface name]|[DB schema name]|[table name]|[task execution id]|[partition number]
Example:
- Production|CRM_DB|public|customer|45|2
TDM_TableLevel LU Tables
Each LUI contains the following tables:
TDM_REF_ROOT
A dynamic SQLite table, which has the same structure as the source table and contains the extracted table records. The naming convention for this table is:
__t_<source table name>
- The following is an example of how a case_note table record is inserted into the SQLite dynamic table:
/*sqlite*/ insert into TDM_TableLevel.__t_case_note (case_id,note_id,note_date,note_text) values(?,?,?,?);
Note:
- In previous TDM versions, tables were saved in the TDM_Reference LU. However, as this LU is no longer used (starting with TDM V9.0), the tables must be re-extracted into the new TDM_TableLevel LU.
Tables — Implementation Steps
Step 1: Deploy the TDM_TableLevel LU
Import the TDM_TableLevel LU and deploy it.
Step 2: Optional — Populate RefList MTable
This step is required for:
- Entities & referential data tasks. Populate the RefList with a list of all available related tables for each LU. The following settings should be populated for each record.
- Table-level tasks for tables whose source and target attributes are not identical.
The RefList MTable contains the following fields:
lu_name — Populated by the LU name to allow selection of the related table in a TDM task based on the task's LUs. Alternatively, if you wish to run the table in a table-level task, populate the lu_name with TDM_TableLevel.
id — An incrementing number.
reference_table_name — Populated with the table name in the source environment.
interface_name — The table's source interface.
schema_name — Populated with the name of the source DB schema that stores the table.
target_ref_table_name — An optional parameter. Populate it when the table names in the source and target differ. If not provided, the target table name is taken from the reference_table_name field.
target_interface_name — The table's target interface.
target_schema_name — Populated with the name of the target DB that stores the table.
table_pk_list — An optional setting. Populated with the list of the target table's PK fields in the RefList object. These fields can be used later for customizing the load flow to run an Upsert on the target table.
truncate_indicator — By default, TDM runs a delete on the table in the target environment before loading it. If you have permission to run a truncate on the target table and need to use the truncate instead of delete (e.g., the target DB is Cassandra), set this indicator to true.
count_indicator — This setting is set to true by default, enabling counting the number of records in the source or target, as a way to monitor task execution. Set this indicator to false, if required, to disable counting records in the target.
count_flow - Populated with the name of a customized flow that returns the table record count. The flow must expose a single external output parameter named tableCount.
Starting with TDM V9.4, the schema_name and target_schema_name fields can be populated using either of the following options:
- Schema name – Specify the schema name directly.
- Global name – Enclose the Global name with
@signs to indicate that the schema name should be retrieved from the Global's value. For example:@CUSTOMER_SCHEMA_NAME@.
Using a Global to populate the schema name is useful when different environments use different schema names.
Note: If the table is partitioned and therefore has a record in the TableLevelDefinitions MTable, populate the TableLevelDefinitions.schema_name field with the Global name as well, using the same syntax as in the RefList MTable (for example, @CUSTOMER_SCHEMA_NAME@).
Click here for more information about MTable objects.
Supporting Different Source and Target Settings
By default, you can populate the RefList MTable to support different source and target settings.
Starting with TDM 10.1, you can also implement a custom Broadway flow to map different source and target settings. The custom flow must have the same inputs and outputs as the DefaultSourceTargetMappingData flow.
To use the custom flow, specify its name in the table_info_mapping_flow field of the TableLevelDefinitions MTable.
Step 3: Catalog
Edit the PII Settings
The TDM table flow uses Fabric Catalog masking. You can edit the PII settings in the Catalog when required.
Run the Catalog to Identify Table Relations and Order
Run the Discovery job on the table's interfaces. Following the job completion, the interface metadata is retrieved from the Catalog.
Optional – Catalog Settings for Table-Level Task Improvements
Add Field Aliases to Table Fields
Starting with TDM 10.1, table-level task filters can display friendly business names for table fields. Field aliases also enable users to share a filter across multiple tables in a task when the corresponding fields have the same business name.
For example, a filter on Financial Transaction Type = 'Payment' can be shared across multiple tables that contain fields with the same business name.
To enable this functionality, tag the relevant table fields with the fieldAlias attribute in the Fabric Catalog. This displays their business names in the filter definition and enables cross-table filter sharing.
See the example below:
For more information, see Manual Overrides on Table Fields in the Catalog.
Add Option Set Analyzer to Discovery
Use the Option set analyzer plugin during discovery to identify non-sensitive (non-PII) fields with a limited number of distinct values in the sampled data. The plugin saves the identified values in a dedicated MTable, making them available as selectable options in table-level task filters.
For example, the vip_status field may contain the following values: Bronze, Silver, Gold, and Platinum. When defining or running a task, users can select a value from the available list or enter a custom value manually.
For more information about how to add filters to tables in a task, click here.
Step 4: Optional — Special Handling
Interface Level Special Handling
The TableLevelInterfaces MTable enables implementors to exclude interfaces from the table-level tasks or define special handling rules for a given interface.
By default, this MTable is populated with the TDM and POSTGRESQL_ADMIN interfaces in order to prevent the TDM tasks from selecting the TDM tables. It is possible to populate additional DB interfaces, either to exclude them from table selection in the TDM task or to apply special handling to their tables. Each DB interface requires its own record. The following settings should be populated for each record:
- interface_name — the interface name defined in the TDM project implementation.
- suppress_indicator — when set to true, the DB tables are excluded from the selection of tables in a TDM task; when set to false, the interface's tables can be selected in a TDM task.
- truncate_indicator — by default, TDM runs a delete on the table in the target environment before loading it. If you have permission to run a truncate on the target table and need to use the truncate instead of delete (e.g., the target DB is Cassandra), set this indicator to true.
- no_schema — this indicator is used for interfaces without a DB schema, where the JDBC connector adds a schema for them. For example: CSV files. The CSV JDBC Connector extension concatenates the 'main' schema name to the file list. Setting this field to true would ignore the concatenated schema when accessing the files.
Tables Implementation — Special Handling
TDM enables customization of the default task execution logic for a specific interface type, interface, schema, or table, including the following capabilities:
- Adding customized flows.
- Configuring commit_size in TableLevelDefinitions to control the number of records reported to the task execution monitor (report every X records).
- Disabling record counting, or adding a flow to count records, to provide the total number of records for processing to the task execution monitor Click here for more details.
- Starting with TDM 9.5, supporting concurrent processing of table partitions.
- Starting with TDM 9.5, supporting in-place masking tasks on tables.
- Supporting table-level tasks using Connectors, for example MongoDB.
Step 5: Optional — Pre and Post Execution Processes
Starting with TDM 10, table-level tasks support pre and post execution processes. To make these processes available for selection when creating a table-level task, the implementor must populate the TableLevelPostAndPreExecutionProcess MTable.
The MTable contains the following fields:
- Process_name — The name of the Fabric flow to execute as a pre or post execution process.
- Process_type — The type of process: pre (runs before the task execution) or post (runs after the task execution).
- Execution_order — The numeric order in which the process runs relative to other processes of the same type. Lower numbers run first.
Once the MTable is populated, the configured processes become available for selection in the task's pre and post execution process settings.
